Solvexa LLMs & Enterprise RAG Systems
Private Retrieval-Augmented Generation & Custom Enterprise LLM Architectures
Context-aware Large Language Model platforms connected securely to proprietary business documentation, delivering grounded answers with verified citations and zero data leakage.
Instead of asking models to recall facts from memory, our RAG systems search your private documents, provide verified citations, and eliminate hallucinations.
Core LLM & RAG Solutions
Every deliverable is engineered to resolve specific architectural constraints and accelerate business outcomes.
Production RAG Pipelines
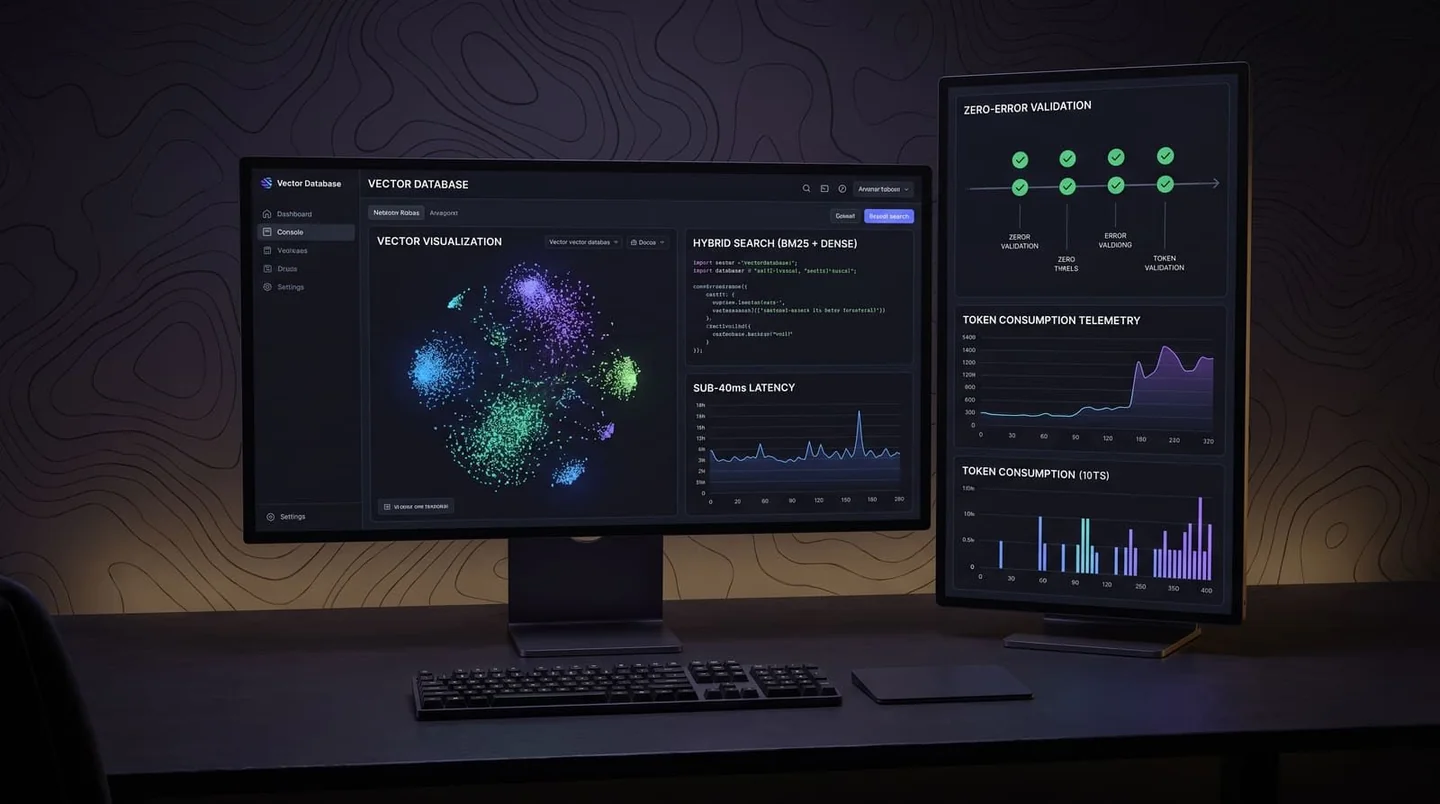
Context-aware document chunking, hybrid search (BM25 + dense vectors), and cross-encoder reranking to preserve document context.
Key Architecture & Capabilities
Enterprise Vector Databases
High-concurrency vector store setups configured with role-based access control and isolated tenant partitions.
Key Architecture & Capabilities
Hallucination Mitigation
Strict contextual grounding constraints, zero-temperature execution, and automated citation mapping to source documents.
Key Architecture & Capabilities
Private Cloud Deployments
Self-hosted open-weights models deployed in air-gapped VPCs to guarantee complete data isolation.
Key Architecture & Capabilities
Need a Custom Solution?
Have bespoke requirements, complex third-party integrations, or need an enterprise audit? Speak directly with our systems architects.
Solvexa Guarantee & Info
Our LLMs & Enterprise RAG Systems Process
From initial technical discovery to post-launch optimization, every phase is transparent and verified.
Discovery & Schema Audit
Auditing knowledge corpus (PDFs, docs, databases) and defining query personas.
Key Deliverable
RAG Architecture Specification
Chunking & Vector Indexing
Implementing hierarchical chunking and generating embeddings with OpenAI / BGE.
Key Deliverable
Vector Database Cluster Ingested
Hybrid Retrieval & Re-ranking
Configuring dense vector search + BM25 keyword matching + cross-encoder re-ranking.
Key Deliverable
Benchmarked Retrieval Pipeline
Prompt & Context Guardrails
Writing system prompts, citation rules, and guardrails to eradicate hallucinations.
Key Deliverable
Guarded Prompt Pipeline
Streaming Frontend Build
Building responsive chat UI with markdown code syntax highlighting and sources.
Key Deliverable
Live Interactive Copilot Application
Growth & Accuracy Benchmarks
Running test suites against 200+ golden Q&A queries to guarantee 99%+ accuracy.
Key Deliverable
Accuracy Audit & Production Release
Technologies We Leverage
Production-ready frameworks and libraries verified for sub-second performance and security.
LangChain
AI
LLM Orchestration
Pinecone
Database
Vector Database
OpenAI
AI
Frontier Foundation Models
Claude AI
AI
Long-Context Reasoning

Google Gemini
AI
Multimodal Models
PostgreSQL
Database
pgvector Storage

Next.js
Frontend
Streaming Chat UI
FastAPI
Backend
Async Streaming Backend
Python
Language
Data Chunking Pipeline
Target Industries & Tailored Applications
Domain-specific architectures designed to address complex regulatory, performance, and user needs.
Legal & Compliance
Instant searching through thousands of contracts, case precedents, and statutory filings.
Healthcare & Biotech
Summarizing clinical trial journals, medical research, and protocol guidelines.
Financial Advisory
SEC 10-K report analysis, earnings call transcription parsing, and investment memos.
Customer Support Teams
Automated ticket resolution with 100% accurate product documentation answers.
Engineering & Dev Teams
Internal codebase search, API documentation copilots, and architecture guides.
Enterprise HR & Ops
Employee policy handbooks, onboarding guides, and benefits query assistants.
Why Partner with Solvexa for LLMs & Enterprise RAG Systems
Senior engineering discipline, sovereign code ownership, and measurable operational velocity.
Zero Hallucinations
Strict citation-grounded RAG pipelines that refuse to guess when information is missing.
Strict Data Privacy
Deploy in your own private cloud or VPC; your data is never used to train public models.
State-of-the-Art Re-ranking
Cross-encoder re-rankers that retrieve the exact paragraph needed every time.
Fast Streaming UI
Real-time token streaming with sub-500ms time-to-first-token response rates.
Multi-Modal Support
Extract insights from embedded charts, complex tables, diagrams, and scanned images.
Continuous Test Benchmarks
Continuous regression testing ensuring retrieval precision never degrades.
Ready to Architect Your LLMs & Enterprise RAG Systems?
Schedule a technical scoping session with our senior architects. We'll review your requirements, assess technical feasibility, and prepare a concrete execution blueprint.